

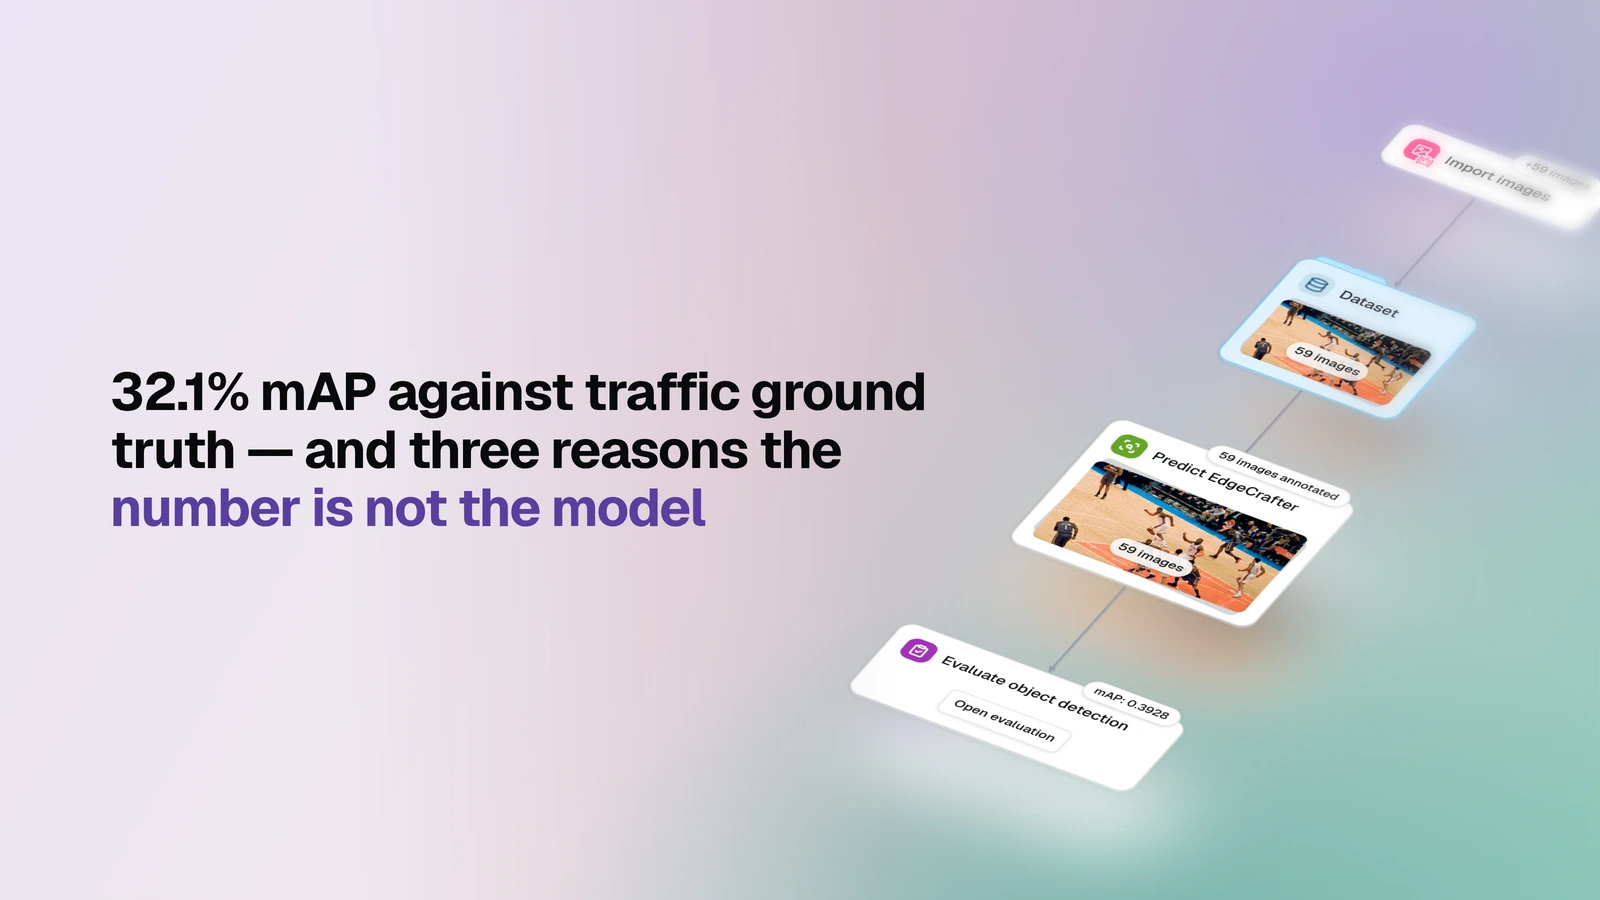
Score one detector against real ground truth and get an honest accept-or-reject read — no other candidate in the mix.
▶ Open this template in OvalBee
Overview
- Model: A single detector, scored against ground truth — no other candidate involved (the architecture is a parameter; the linked run evaluated EdgeCrafter)
- Task: Object detection
- Input: A labeled image set with real ground truth, plus the one model to evaluate — both supplied as parameters
- Pipeline: pick the labeled set → run the detector on it → score its predictions against the same ground truth
- Output: mAP, AP50, AP75, F1, precision and recall, a per-class breakdown wherever the data supports it, and prediction previews against ground truth
When you need it
This is the template for accepting or rejecting one specific detector — not choosing between several, just an honest read on whether this one model is good enough. It's also the template for checking, periodically, that a model already in production still holds the bar it was accepted on, and because it scores exactly one model, a full diagnostic — where it's strong, where it's weak, down to individual classes — is the point of the report rather than something trimmed away, unlike this library's comparison templates, where a single model's own detail is kept to a link instead of taking over the page.
What you need
A labeled image set with real ground truth, and the one model you want to evaluate. Both are parameters — any labeled image domain and any detector works. If your labeled set isn't in OvalBee yet, bring it in with one of the import templates first.
How it works
| Step | What happens |
|---|---|
| Dataset | Pick the labeled image set to score against, ground truth included |
| Predict | The detector runs on every image |
| Score | Every prediction is measured against the same ground truth |
What a run gives you
A full accuracy read on one model: mAP alongside AP50, AP75, F1, precision and recall, plus a per-class breakdown everywhere the test set has enough ground truth to back it up — so a weak class shows up as a specific, actionable finding rather than getting buried in one aggregate number. Prediction previews sit alongside the numbers, so you can see ground truth against the model's own boxes on real images, not just read a score.
Because this runs as one OvalBee acceptance check, it's built to be repeated: point it at the model again after a retrain or a version bump, and it scores against the identical reference the same way, so confirming a model still holds the bar doesn't mean rebuilding the check by hand every time.
Related templates
- Detector comparison — the multi-candidate version of this same scoring step, for choosing between several ready-made models instead of accepting one
- Fine-tuned vs COCO (images) — uses this same kind of scoring step twice, to weigh a model you trained yourself against a ready-made baseline
- Two trained detectors is a sibling template in this library — the same accept/reject question, applied to two of your own trained models instead of one ready-made candidate — not yet published here